Note: many of these blog posts had initial research and drafts done by the Blog Writer multi-agent application that serves as a demo for these articles. All were then edited by me.
Posted inAI, Essentials|Comments Off on Agentic Table of Contents (so far)
In a previous blog post I walked through a RAG example using Microsoft Agent Framework so that we could do a semantic search against our documents.
However, Bruno Capuano (Microsoft) and I went over this for my latest video with him. His reaction was that what I was doing was “right” but that I was working too hard, doing things that the Microsoft.Extensions.AI.Templates would do for me—or at least make simpler. He pointed me to the quickstart for AIChatSample.
The analysis in the quickstart is out of date, and there are significant changes. Here is an analysis of the latest version of the code. You can get the code itself from the quickstart, but note that I use llama.cpp rather than Ollama.
The rest of this post walks through the RAG implementation in AIChatSample, a Blazor chat application that uses OpenAI-compatible endpoints provided by llama.cpp. The emphasis is on the full path: configuring separate chat and embedding clients, ingesting and chunking documents, saving vectors in SQLite, retrieving relevant chunks, and turning those results into visible citations.
The application at a glance
The main pieces are registered in Program.cs. The app creates an IChatClient for conversation and an IEmbeddingGenerator<string, Embedding<float>> for vector embeddings. Both are built from configured endpoint and model values using the OpenAI .NET client adapters. Although the clients use the same API style, they do different jobs and may run on separate llama.cpp servers: the chat endpoint generates responses and handles tool calls, while the embedding endpoint converts text into vectors.
That distinction matters. RAG needs embeddings when documents are prepared and again when a user query is searched. The chat model is not the search index, and a chat-only server cannot replace the embedding service. This sample configures an all-MiniLM embedding model that produces 384-dimensional vectors. The vector schema declares that same dimension, so the model and stored collection must remain compatible.
Program.cs also registers a SQLite vector store and a collection for IngestedChunk, then registers DataIngestor and SemanticSearch as singleton services. The document source is the app’s wwwroot\Data directory. This keeps the sample’s architecture compact: the same directory supplies documents to the ingestion pipeline and later supports the UI’s links back to source files.
Stage one: read and normalize documents
The RAG pipeline begins when a search is needed, not when the web host starts. In Chat.razor, the assistant is offered a LoadDocuments tool and instructed to use it before searching. The tool calls SemanticSearch.LoadDocumentsAsync, which starts the ingestion task the first time and retains that task for later calls. This means repeated tool invocations share the same load operation rather than starting a new one each time.
DataIngestor.IngestDataAsync assembles the ingestion pipeline from three parts: a reader, a chunker, and a vector-store writer. It scans the configured directory using the *.* search pattern. The custom DocumentReader delegates Markdown to the Markdown reader and PDFs to PdfPigReader. Markdown is assigned the text/markdown media type; PDFs are handled by the PDF reader. Unsupported media types fail explicitly rather than being silently treated as plain text.
The PDF reader opens each document with PdfPig, walks through its pages, extracts letters, groups them into words, and then groups words into text blocks. Each block becomes a paragraph element in a section labeled with the PDF page number. That page-aware structure gives the ingestion pipeline organized text to work with instead of treating a PDF as a single opaque binary file. The document reader also normalizes fully qualified identifiers to paths relative to the data directory, which is useful later when a result needs to identify its source document.
Stage two: split the text and embed it
Searching an entire book or long report as one record would be imprecise and could exceed what is useful to pass to a model. AIChatSample therefore uses SemanticSimilarityChunker in DataIngestor. The chunker uses the configured embedding generator and a tokenizer (TiktokenTokenizer configured for gpt-4o) to create manageable pieces. Semantic chunking aims to keep related content together, rather than cutting text only at arbitrary fixed character boundaries. The exact chunking behavior is provided by the ingestion library, while the app supplies the model and tokenizer it should use.
Each resulting chunk is represented by IngestedChunk. Its fields capture a unique key, the source DocumentId, the chunk’s Text, and an optional Context field. The Vector property returns the chunk text, which allows the vector-store integration to generate an embedding from that text. The vector property is annotated as a 384-dimensional vector with cosine distance. In effect, each stored item contains both searchable semantic representation and the original text needed to give the language model actual evidence.
The VectorStoreWriter is configured with the collection name, dimension count, and distance function from the record type. It writes the pipeline’s chunks into the SQLite vector store. The writer is set to non-incremental ingestion, so the application explicitly does not configure incremental ingestion for this pipeline. Persisting the collection locally means later searches can query the indexed chunks without reconstructing an in-memory index for every question.
Stage three: find relevant chunks
When the model calls the Search tool, Chat.razor passes the user’s search phrase and an optional filename filter to SemanticSearch.SearchAsync. That method first awaits LoadDocumentsAsync, ensuring ingestion is complete before vector search proceeds. The vector collection then searches for the phrase and asks for up to the requested number of results. If a document ID was supplied, a filter restricts matches to that document; without one, search spans the collection. The chat tool requests a maximum of five results.
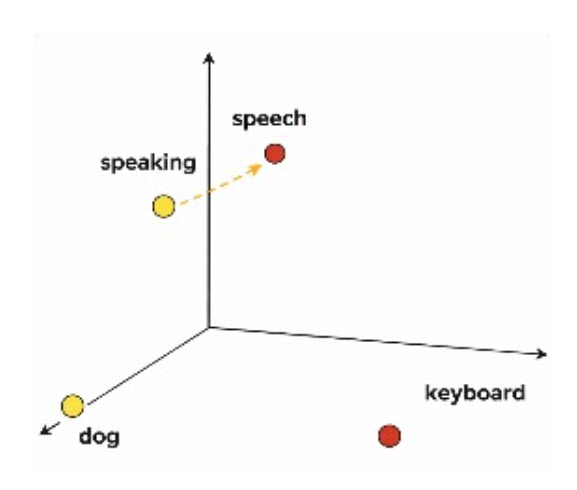
Conceptually, the embedding service maps the query into the same vector space as the document chunks. The vector store compares that query vector with stored chunk vectors using cosine distance and returns the nearest matches. The application returns the matching records, including their source document IDs and text. This is semantic retrieval: the query can find conceptually similar passages even when they do not repeat the exact wording of the question.
The top results are not themselves the final answer. They are evidence to be passed back to the model. The Search tool formats each result as a small XML-like fragment containing a filename and the text. This gives the model explicit source boundaries and the passage content it can use when drafting a response.
Stage four: let the model use tools and answer
The chat page constructs a system prompt that restricts the assistant to questions about retrieved information. It tells the model to load the documents, use search, and cite search results. In OnInitialized, the page exposes the LoadDocumentsAsync and SearchAsync methods as AI functions through AIFunctionFactory. Program.cs wires function invocation into the chat client, so the model can request these application functions during a conversation.
This is an important distinction from a design where the app blindly retrieves a fixed set of chunks for every incoming message. Here, the model can first decide to load and search, and it can provide a search phrase and optionally a filename. The UI gives it tool descriptions and argument descriptions to guide those decisions. Once the tool returns passages, the model can compose a natural-language answer based on them. It is still the model that writes the response; retrieval supplies relevant, external context.
Responses stream into the Blazor page through GetStreamingResponseAsync. The page accumulates text updates and also keeps non-text content such as function-call information in the conversation. The UI can therefore show progress such as document loading or the current search phrase while the assistant works, rather than waiting for the entire response before showing anything.
Stage five: citations connect an answer to its source
The prompt asks the model to finish with citation tags in a particular format, using a short exact quote from the retrieved result. ChatMessageItem looks for those tags after a response is complete. It extracts the filename and quote, then renders each as a ChatCitation component. The component creates a link to an appropriate viewer: Markdown opens in the Markdown viewer with a text-fragment target, while PDF opens in the PDF viewer with a search fragment.
This makes citations more than decorative labels. A reader can follow the source filename and quote back to the underlying document. The prompt’s five-word quote limit is a small convention that encourages concise evidence anchors, while the actual source passage remains available to the model during answer generation.
There are practical limits to note. The citation is generated by the model and parsed from its text, so the prompt guides the format but does not by itself guarantee that every quote is valid or that the answer is fully supported. Retrieval quality also depends on document extraction, chunk boundaries, embedding-model suitability, and the number of results. For production use, teams often add checks that verify a cited quote appears in the retrieved text, evaluate retrieval quality against representative questions, and add metadata filters for access control or document categories.
How to run and evolve the RAG sample
The README describes configuring two llama.cpp servers: one chat-compatible model and one embedding model that supports the OpenAI-compatible embeddings endpoint. The app needs both endpoints reachable. The collection schema in IngestedChunk expects 384-dimensional embeddings; changing the embedding model may require updating that dimension, deleting and recreating the local vector database, and re-ingesting the documents so query vectors and stored vectors remain compatible.
To add another document type, extend DocumentReader with a reader for its media type and decide how its structure should be represented as sections and elements. To tune retrieval, measure the quality of chunking, consider metadata such as page numbers and titles, and test whether the chosen result count gives the chat model enough evidence without overwhelming the prompt. To make citations more precise, preserve useful location metadata through ingestion and include it in the result returned to the model.
The central idea is straightforward: read documents into structured text, split that text into semantically useful chunks, embed and persist the chunks, retrieve the nearest matches for a query, and give those passages to a model that can answer and cite them. AIChatSample implements each step in a small set of services and connects the steps through model-invoked tools. Follow one question through those stages and RAG becomes less of a buzzword and more of a concrete data flow—from files in Data to an answer with a trail back to its evidence.
This analysis was composed by BlogWriter and then edited by me. Please note that AIs can make errors and this analysis is offered as is.
Posted inAI, Essentials|Comments Off on RAG and Microsoft Agent Framework Step By Step (2)
Want to build an extension to Spec Kit? This comprehensive guide walks you through everything you need: a ready-to-drop extension layout, a complete extension.yml manifest, a slash-command file, a lifecycle hook that runs a C# helper, a full C# console app (source + csproj), install scripts, CI to build multi-platform artifacts and package the extension, plus troubleshooting, testing, and security advice.
What you’ll get (artifacts shown in this guide)
A consistent extension folder layout you can copy into a project-level .specify/extensions/ directory for local testing. (If your environment uses a different extension directory, replace .specify accordingly.)
Full extension.yml manifest.
A slash command file: addon/commands/speckit.extn.myfeature.md.
A lifecycle hook descriptor: addon/hooks/after-plan.yml and platform run wrappers.
A small C# console app (MyFeatureRunner) that reads a spec path and writes structured JSON to stdout.
Install scripts (install.sh, install.ps1) and OS wrappers (run.sh/run.ps1) to select the right binary.
A GitHub Actions workflow that builds platform binaries and packages a ZIP for publishing.
Tests (xUnit) that exercise the analyzer logic (no Python anywhere).
This guide assumes you already understand what Spec Kit and presets are and focuses on the who/what/where/how of authoring, testing, and publishing a preset. The instructions are concrete and practical — including a minimal manifest example, the recommended folder layout, local test workflow, a tiny C# validation snippet, and packaging/publishing notes.
Your design docs look different across teams. Some repos forget the QA gate. Integrations (Jira, CI) are half-baked and duplicated as bash scripts. Onboarding a new engineer requires five manual steps to wire the same set of templates, commands, and pipelines.
Spec Kit exposes four primitives that solve these problems in a structured, maintainable way:
Presets fix content and wording (make docs consistent).
Extensions add behavior and integrations (run code, call Jira/CI).
Workflows orchestrate multi-step, resumable pipelines (add gates and state).
Bundles package and version a curated set of the above (one-command onboarding).
This post explains each primitive plainly, shows concrete manifests and examples (CLI + Visual Studio Code), and gives authoring, troubleshooting, and operational guidance so you can pick the right tool for the job.
Prompts allow you to manage the exact instructions your chat models receive and let apps pick those instructions at runtime.
That’s the core value of “prompts” in the Model Context Protocol (MCP). MCP prompts let a server publish reusable, argument‑driven prompt templates that clients (including Microsoft Agent Framework agents) can discover, retrieve, and use in LLM chat calls—so behavior, UX, and auditing are consistent across apps.
When working with agents (e.g., in Microsoft Agent Framework) it is easy to be confused as to when the LLM is called. Since calling the LLM (and getting responses) costs money (in the form of expended tokens) it is important to understand this relationship.
An agent in the Microsoft Agent Framework (MAF) talks to an LLM whenever it needs to: (1) decide what to do or generate text (initial planning/response generation), (2) decide whether to call a tool and provide its arguments (function/tool calling), and (3) incorporate tool outputs and continue reasoning or synthesize the final reply.
A single agent run commonly produces multiple model calls in a loop: planning → tool call(s) → synthesis → (repeat if needed).
MCP (Model Context Protocol) is an open protocol that standardizes how AI hosts (models/ or agents) discover and call external “tools” and contextual data sources. Instead of building bespoke integrations for every service, an AI host can discover tools exposed by MCP servers and invoke them using a single, consistent API (tool list + function invocation/streaming).
MCP server: a service that publishes tools (callable functions, data endpoints, long-running operations) via MCP over supported transports (stdio for local child processes, HTTP + SSE for remote/streamable). Servers are the canonical place to register capabilities agents can discover. *SSE is an HTTP‑based streaming mechanism where the server keeps an HTTP connection open and continuously pushes events to the client
MCP client: the client-side runtime your agent uses to discover and call tools exposed by one or more MCP servers. The MCP C# SDK provides transports and helpers to produce AIFunctions that integrate with Microsoft’s Agent Framework function-calling model.
Adding RAG to Microsoft Agent Framework is both straightforward and confusing. OK, that makes no sense, but I’ve been struggling to understand all the steps. Here’s a first approximation, more to come in future posts (and I have a video coming with Bruno Capuano and Jon Galloway on this very subject). There are also a bunch of RAG blog posts that I’ve already posted; you can find the list here.
TL;DR
Learn the simple C# steps to wire Retrieval-Augmented Generation (RAG) into Microsoft Agent Framework (MAF).
Includes a runnable, self-contained console stub that chunks documents, stores them in-memory with metadata, runs a demo similarity search, and returns answers plus source citations.
Swap the demo token-overlap search for real embeddings + a vector DB in production and then pass the search delegate into MAF’s TextSearchProvider.
Run a full Microsoft Agent Framework (MAF) agent entirely on-device to eliminate round trips to the cloud, reduce latency, avoid egress costs, and keep sensitive data private. With Foundry Local you can run optimized local model variants (ONNX/WinML) and wire them directly into MAF.
In this guide you’ll get a working quickstart (Windows .NET 7 + WinML and a cross-platform Python example), exact commands to install and download a model, copy‑and‑paste code, hardware/driver tips, observability and troubleshooting checks, CI/CD advice, and production‑ready recommendations.
TL;DR Use the Responses client for new projects if you want the newest, richest hosted tools and structured outputs; use the Chat Completion client when you need maximum backward compatibility or are constrained to the Chat-completions API (for example, Go-only paths or older models).
Why this matters Choosing between a Responses client and a Chat Completion client in Microsoft Agent Framework affects which provider API and hosted tools your agent can use, how easy it is to migrate, and what models/back ends you can target. That can influence development effort, feature availability (hosted code execution, file search, image generation, structured outputs), and runtime portability.